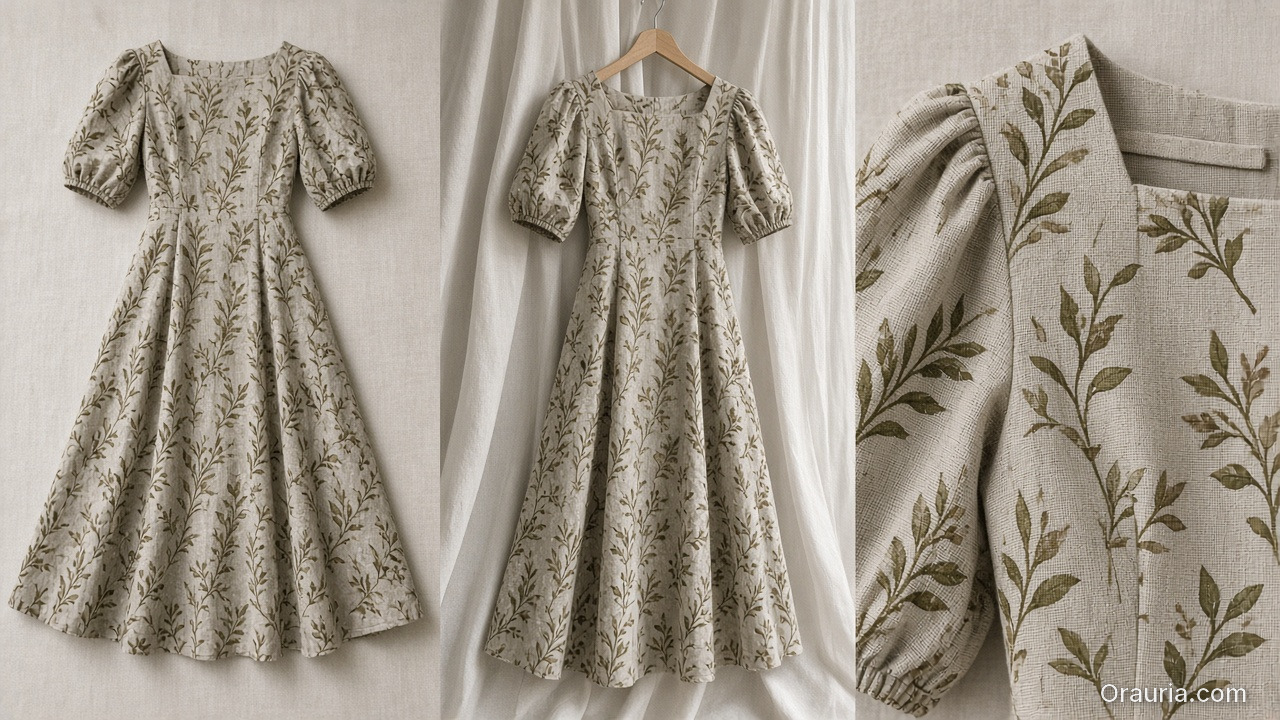
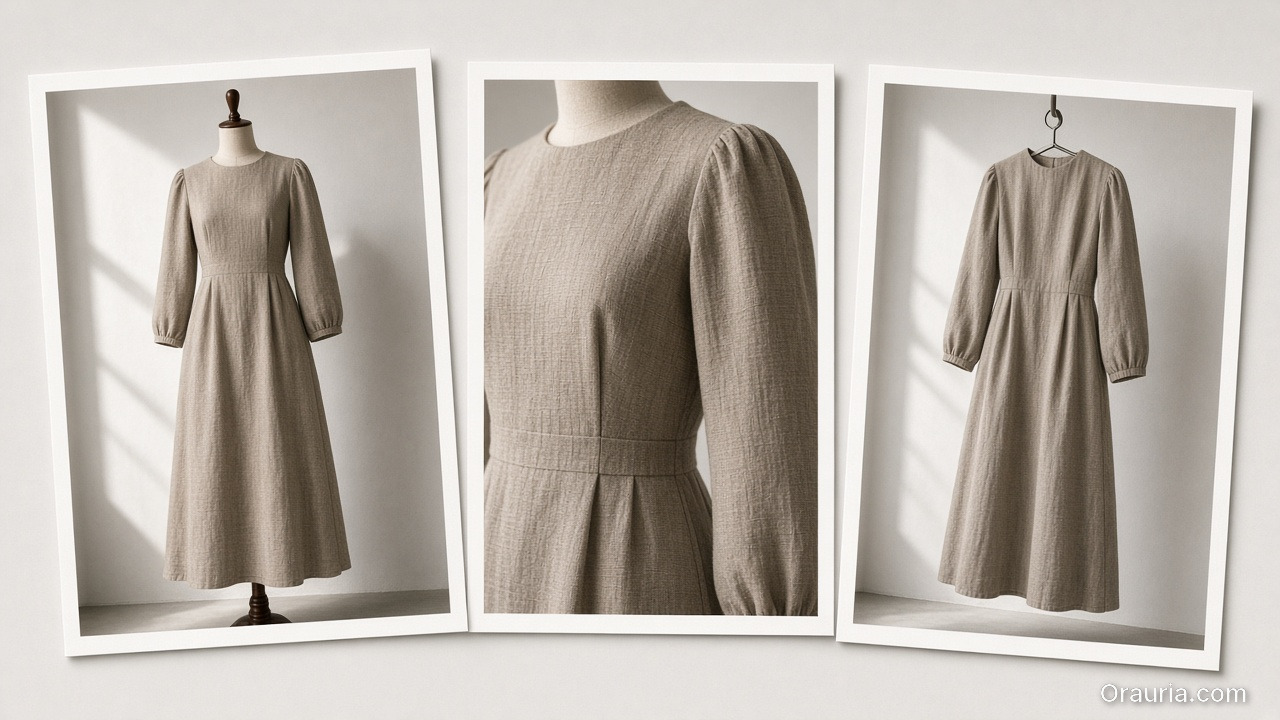
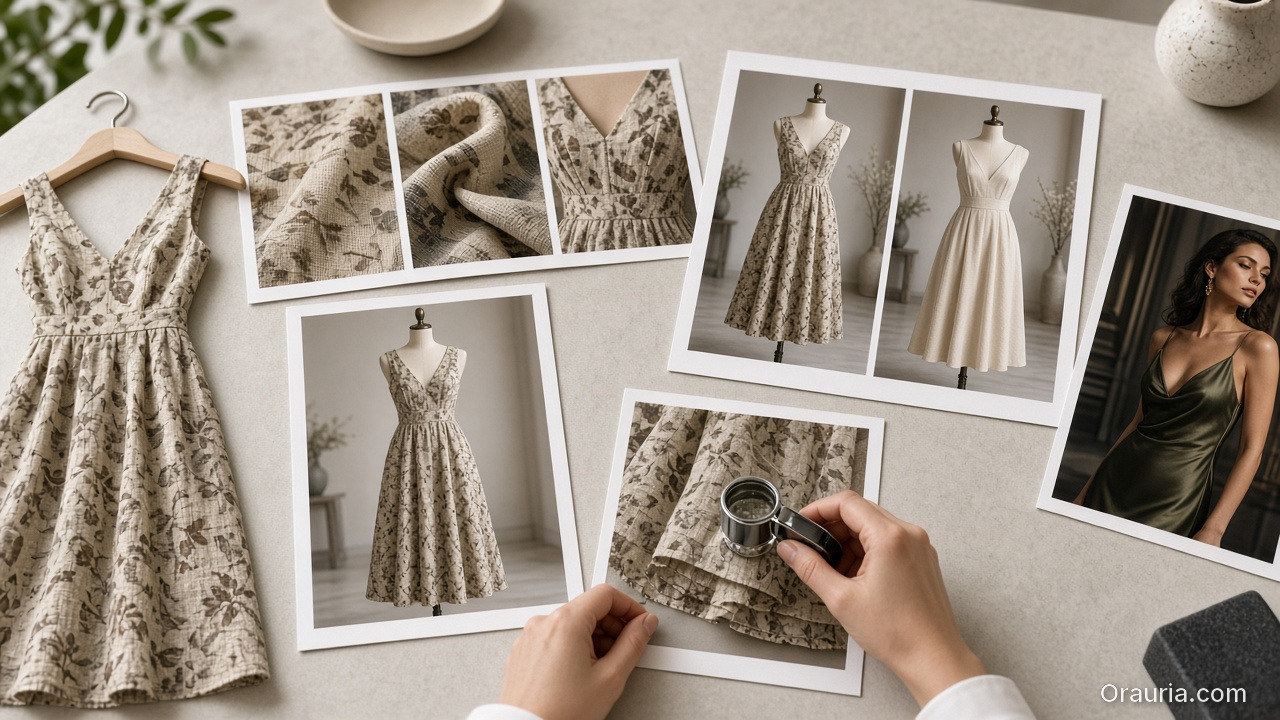
Virtual try-on promises “see it on me.” Too many AI ads deliver “see a stranger wearing almost your SKU.” Necklines drift. Sleeve lengths invent themselves. The face is gorgeous — and the garment is fiction.
AI virtual try-on ads work when you treat try-on as fit storytelling: garment truth first, character second, filter effects never.
Key Takeaways
Try-on is a garment fidelity problem with a human in frame — not a beauty filter with clothes attached.
Garment fidelity under zoom, stable character, and clear Demo/Proof jobs — not maximal beauty scores.
Do I need a different model for try-on vs packshots?
Choose for the fidelity bottleneck after direction. Try-on usually needs stronger reference lock than lifestyle exploration.
Can try-on replace size charts?
No. It supports intuition. Charts and measurements remain mandatory.
How many try-on frames per SKU?
One approved on-body hero + one detail proof beats six drifted beauties.
Conclusion
Stop shipping face filters in dresses. Ship fit stories.
Lock the garment. Gate the seams. Keep one character. Use try-on where Demo and Proof matter. That is how AI virtual try-on ads earn clicks that survive the PDP.
Amazon does not buy your moodboard. It buys slot performance: a compliant main image, a gallery that answers doubts, and A+ stills that explain without breaking catalog rules. Teams that AI-generate “seven pretty heroes” still lose the Buy Box war on clarity.
AI Amazon listing images work when you treat the gallery as a system of jobs — not a folder of vibes.
Key Takeaways
Main image = compliance + recognition. Secondary slots = doubt removal. A+ = story without replacing Truth.
Listings with richer image sets convert more strongly in large studies (~50% higher with 5+ images vs thinner galleries in Catchlab-cited 2026 roundups).
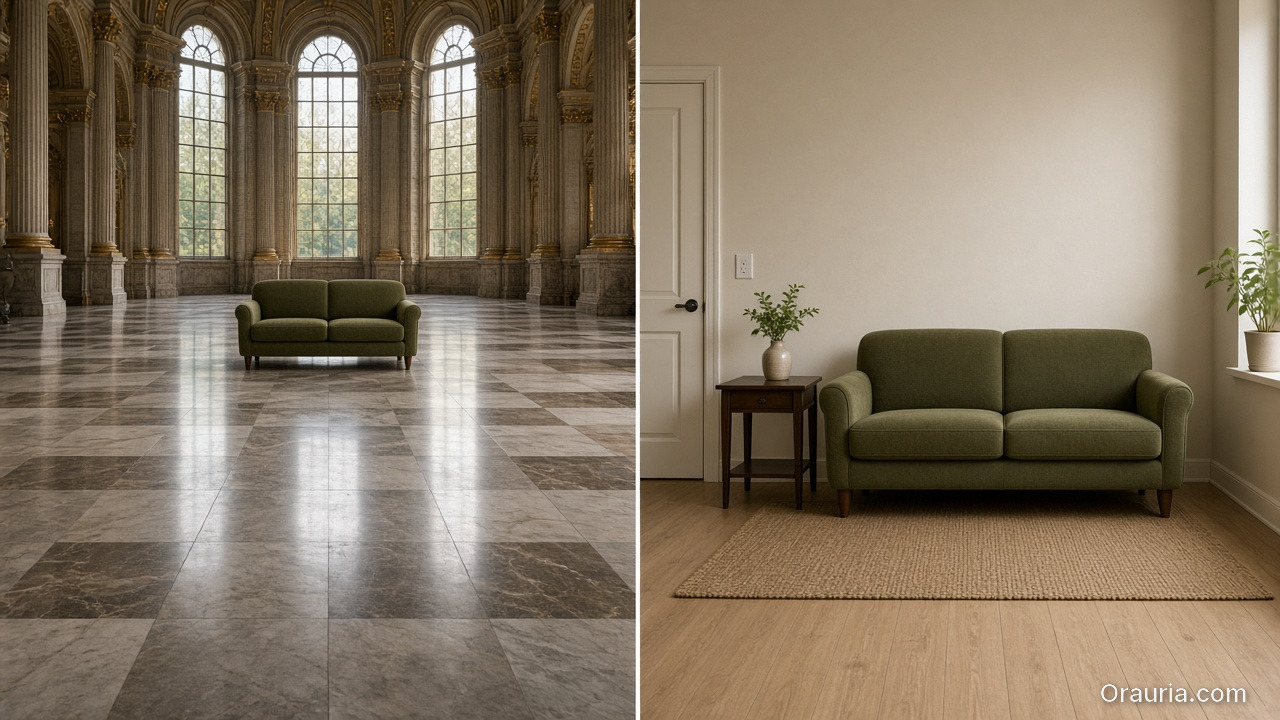
A sofa on pure white tells dimensions badly. A sofa in a cathedral living room tells lies well. Home and furniture ecommerce lives in that tension: buyers need context, but context that invents square footage creates “looked bigger online” returns.
AI home product staging is the discipline of placing SKUs in believable rooms with scale honesty, locked light, and gates — not generating dream interiors that your warehouse cannot ship.
Key Takeaways
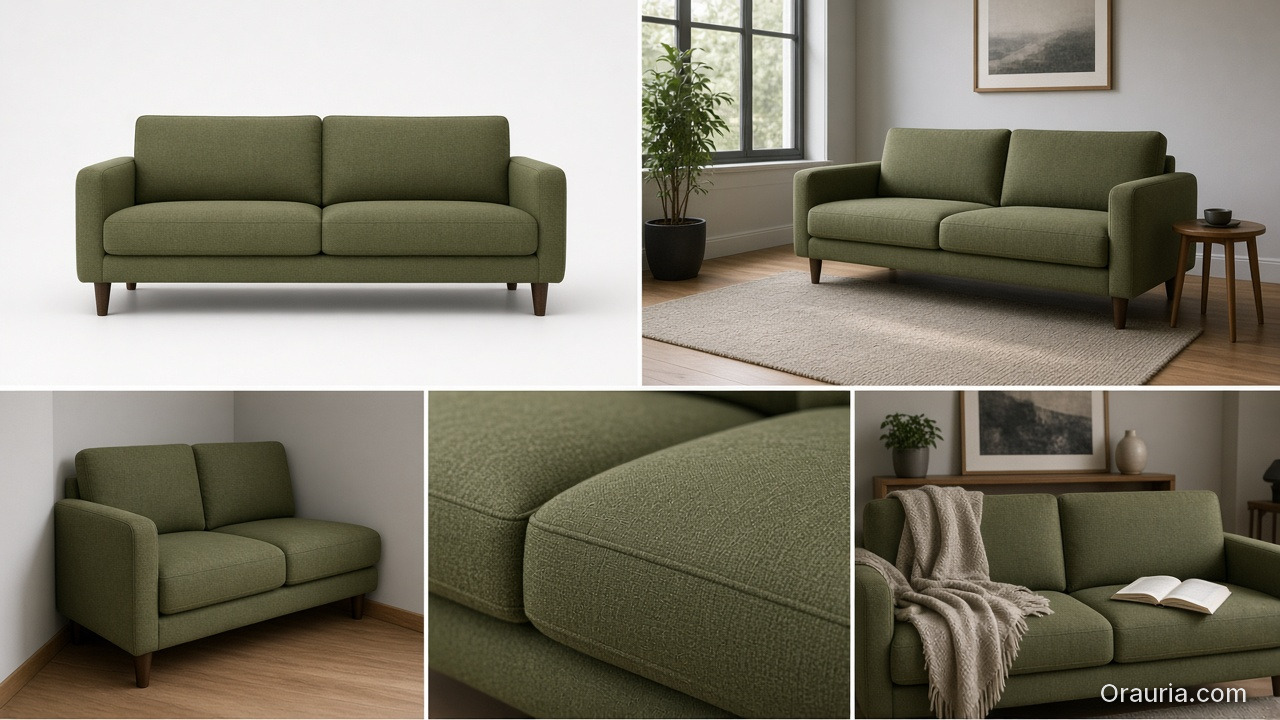
White-only home catalogs under-inform; fantasy rooms over-promise. Use dual-layer galleries like visual commerce 2026.
Stage with known scale anchors (door, outlet, side table) and real product dimensions in the brief.
Map rooms like beauty maps rituals — a context grid before generate (SCENE).
Geometry still matters for legs, seams, and hardware (hard goods QA when parts are precise).
Why Does Home Staging Break Trust Online?
Because furniture is purchased as space math.
Staging sin
Buyer consequence
Oversized rooms
“Tiny in real life” returns
Wrong camera height
Proportions feel off
Mixed design eras
Brand looks incoherent
Soft rug hiding feet
Leg style unknown
Invented materials on props
Cart confusion
Lifestyle lift is real in ecommerce image research — but only when lifestyle stays honest.
Home staging is not interior design porn. It is dimensional storytelling: how big, how it sits, how it lives with ordinary walls.
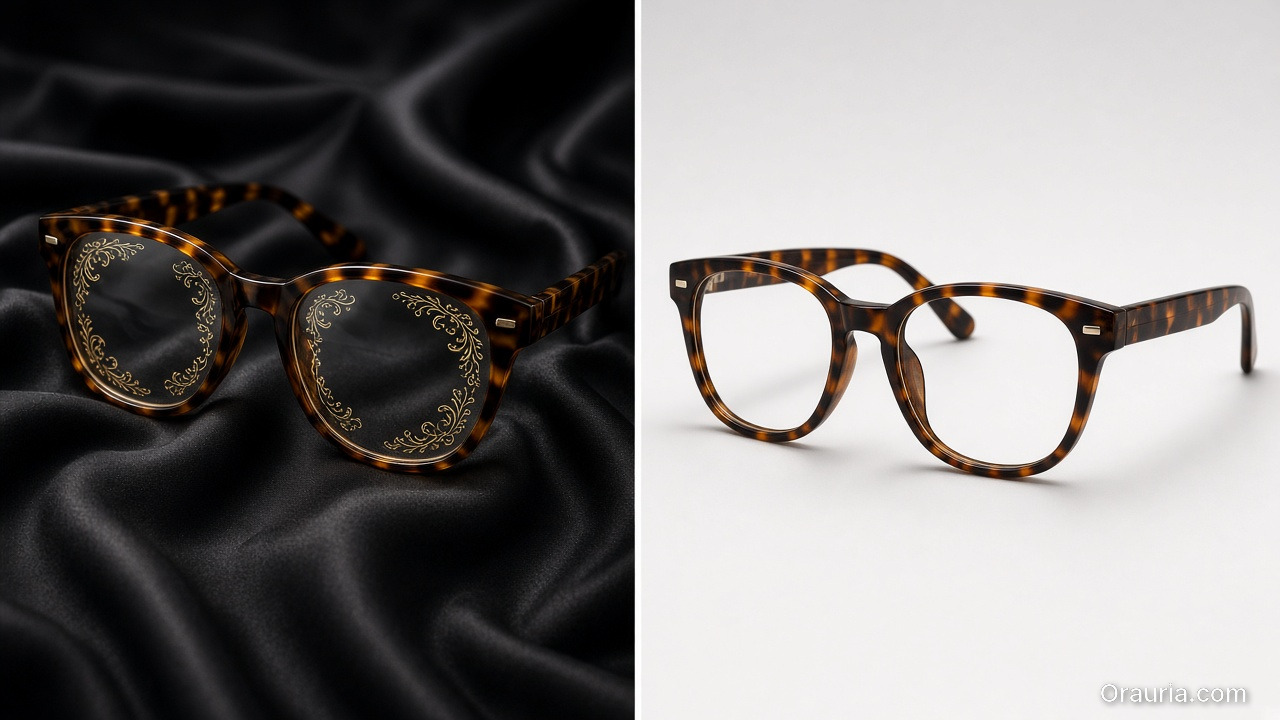
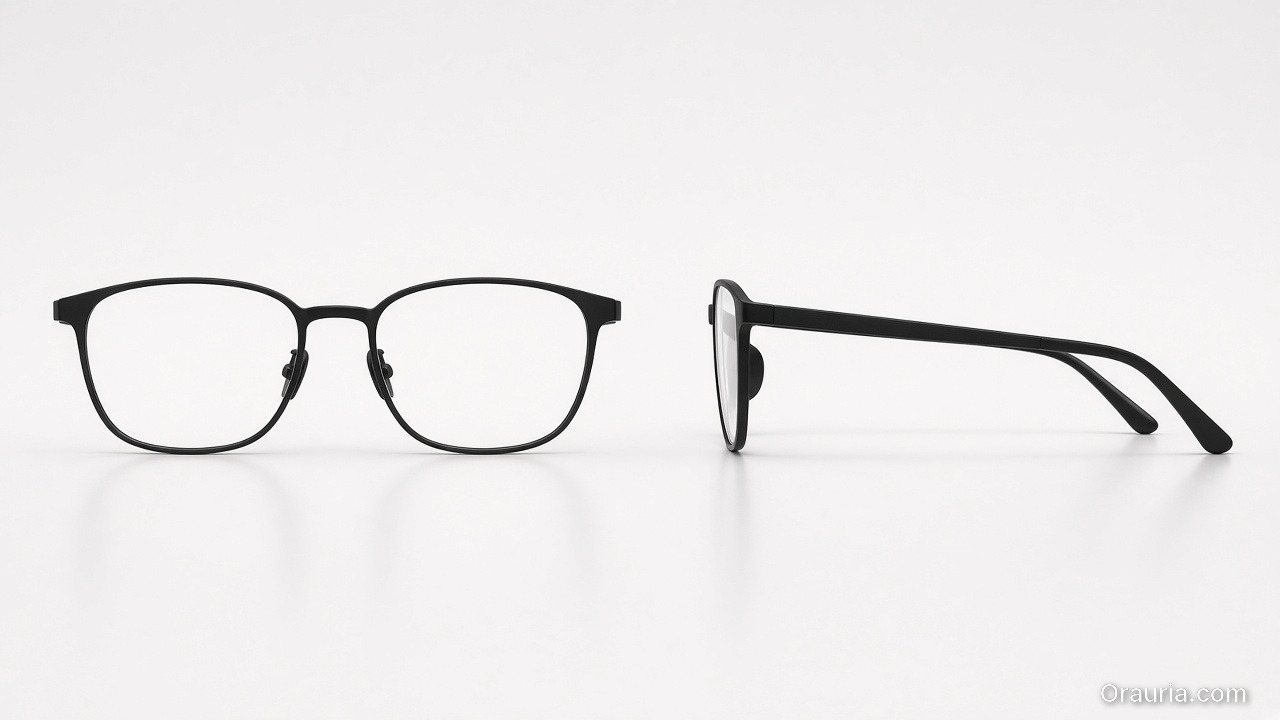
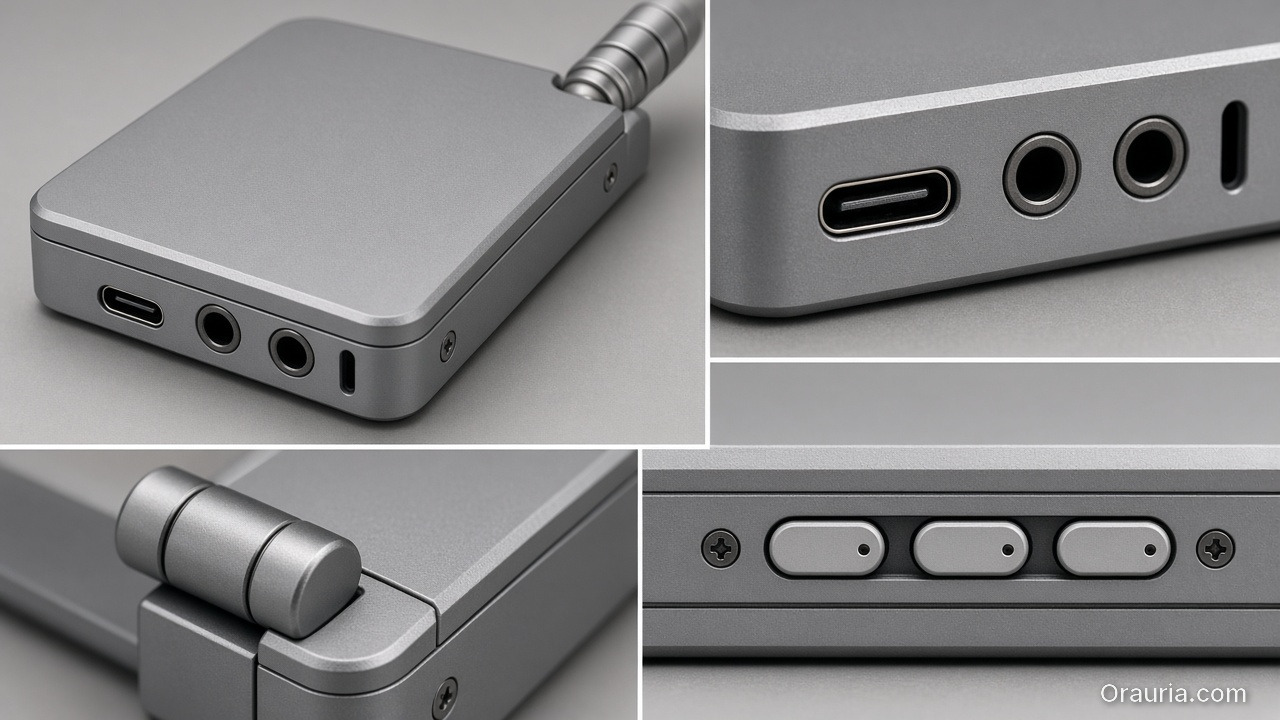
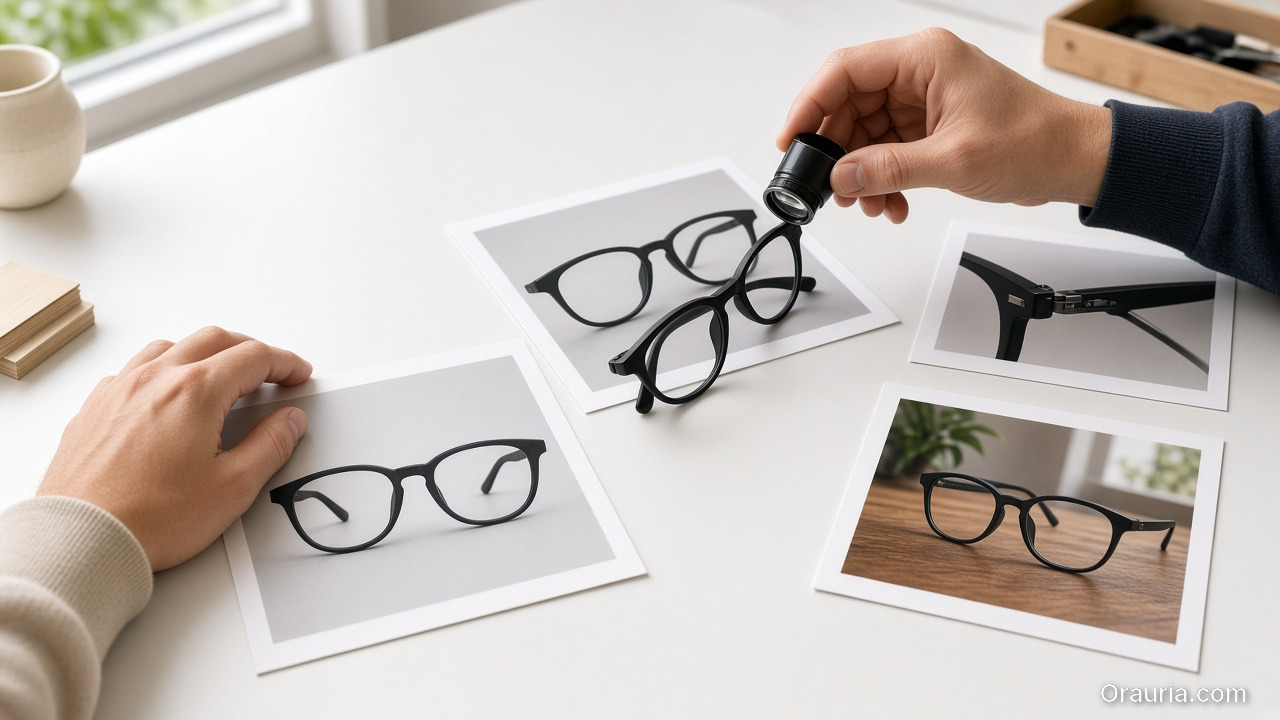
Beauty SKUs forgive a soft edge. Eyewear does not. A millimeter of temple warp, a lens reflection that invents a logo, a button row that gains an extra key — and the listing becomes a liability.
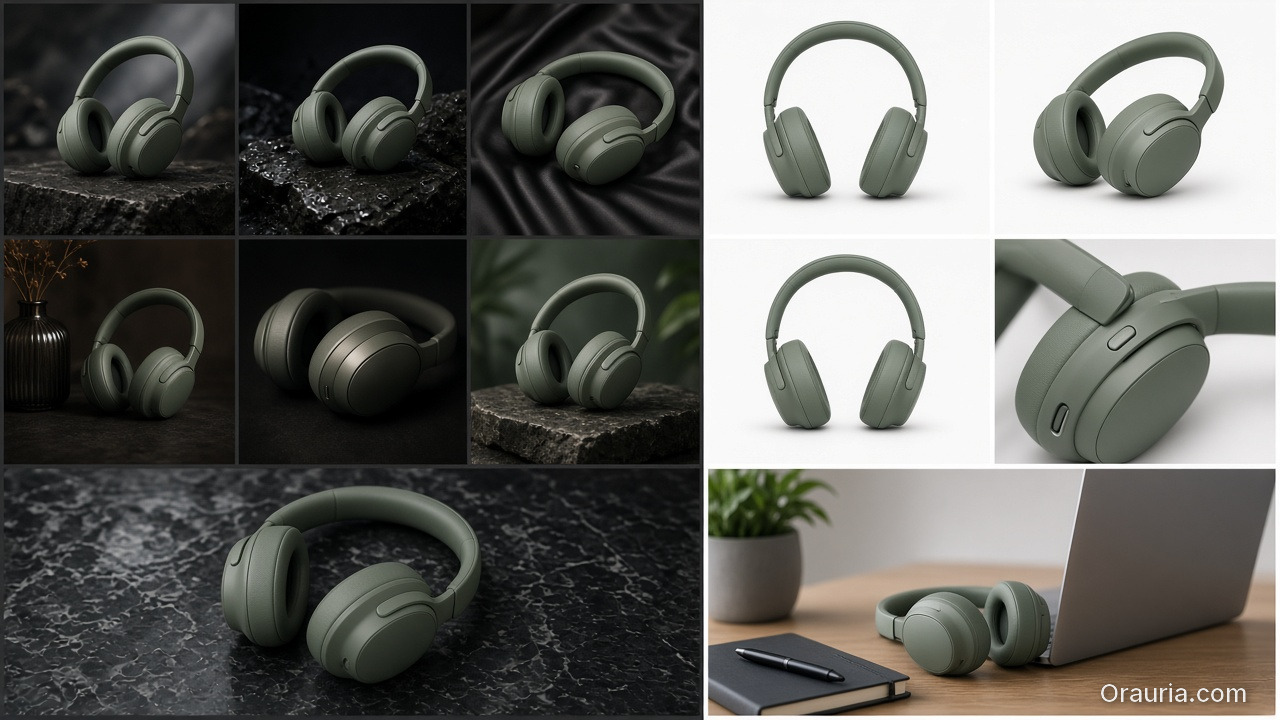
AI hard goods product images fail when teams apply fashion/lifestyle prompting to precision objects. Hard goods need geometry QA as a first-class gate: silhouette, symmetry, ports, hinges, and print — before any lifestyle world.
Key Takeaways
Hard goods are spec products. Buyer trust is dimensional, not only emotional.
Run a geometry checklist before beauty, upscale, or lifestyle extension (packshot thinking).
Prefer reference-heavy generation; explore mode is for backgrounds after the object passes (reference vs explore).
Upscale only after QA (upscale after QA) — sharpening warped hinges makes rejects look confident.
Why Do Lifestyle Prompts Break Hard Goods?
Because soft prompts optimize for vibe. Hard goods optimize for match-to-unboxing.
Soft-goods bias
Hard-goods reality
Fabric drape can vary
Hinge angle cannot
Skin tone mood
Port count is binary
“Premium glow”
Specular lies on lenses/metal
Approximate logo
Exact wordmark + icon
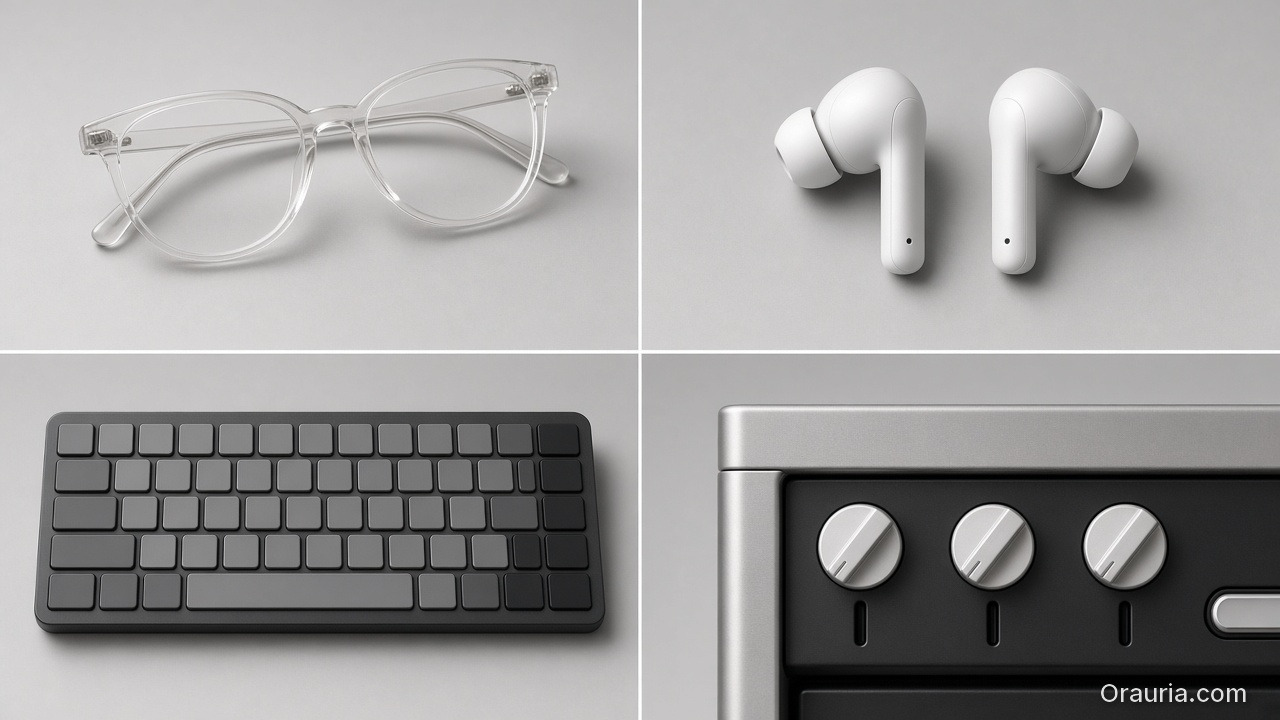
Eyewear, watches, earbuds, keyboards, tools, and small appliances sit on the hard side of that table.
For hard goods, the hero image is a contract drawing with light — not a moodboard with a product stuck on top.
Geometry QA Checklist (Pass Before Beauty)
Silhouette
Outer shape matches reference
No melted corners, no missing tips (eyewear temples)
Symmetry / alignment
Left-right balance on glasses, buds, paired objects
Button grids aligned
Functional parts
Ports, hinges, switches, screws present and correct in count
No “extra USB” hallucinations
Optics / materials
Lens transparency plausible (no opaque glass unless product is)
Metal vs plastic read correct
Print / icons
Logos and iconography correct — or intentionally out of frame
Fail any row → reject. Do not lifestyle it “to hide the error.”
Playbook: Spec-True Then Scroll-Stopping
Capture honest refs — front, 45°, detail of hinge/port
For ads, keep scene jobs — but Truth frames carry the SKU.
Category Notes
Category
Extra risk
Extra gate
Eyewear
Lens reflections invent logos
Check both lenses
Earbuds / wearables
Stem length drift
Side-by-side with ref
Keyboards / controllers
Key count / layout
Count visible keys
Small appliances
Cable / button myths
Detail crop of controls
Soft CTA
Build spec-true packshots before campaign worlds: Packshot · Ecommerce
Frequently Asked Questions
What counts as hard goods for AI product images?
Products where dimensional accuracy and part count matter to purchase and returns — eyewear, electronics, tools, precision accessories.
Can I still use lifestyle scenes?
Yes — after the object passes geometry QA. Lifestyle is extension, not repair.
Should I use a different AI model for hard goods?
Choose for fidelity bottleneck after direction — not because the category is trendy. See model-after-direction guidance.
How many reference angles do I need?
At least front + 45° + one detail of the failure-prone part (hinge, port, lens).
Conclusion
Hard goods do not need softer prompts. They need harder gates.
Geometry first. Beauty second. Lifestyle third. Upscale last. That is how AI hard goods product images survive zoom, returns, and marketplace scrutiny.
Most creator burnout with AI is not about tools. It is about starting from zero every post.
New hook. New face almost. New lighting world. New caption energy. The algorithm may reward the spike. The audience cannot form a memory. You become a content lottery — occasionally brilliant, never cumulative.
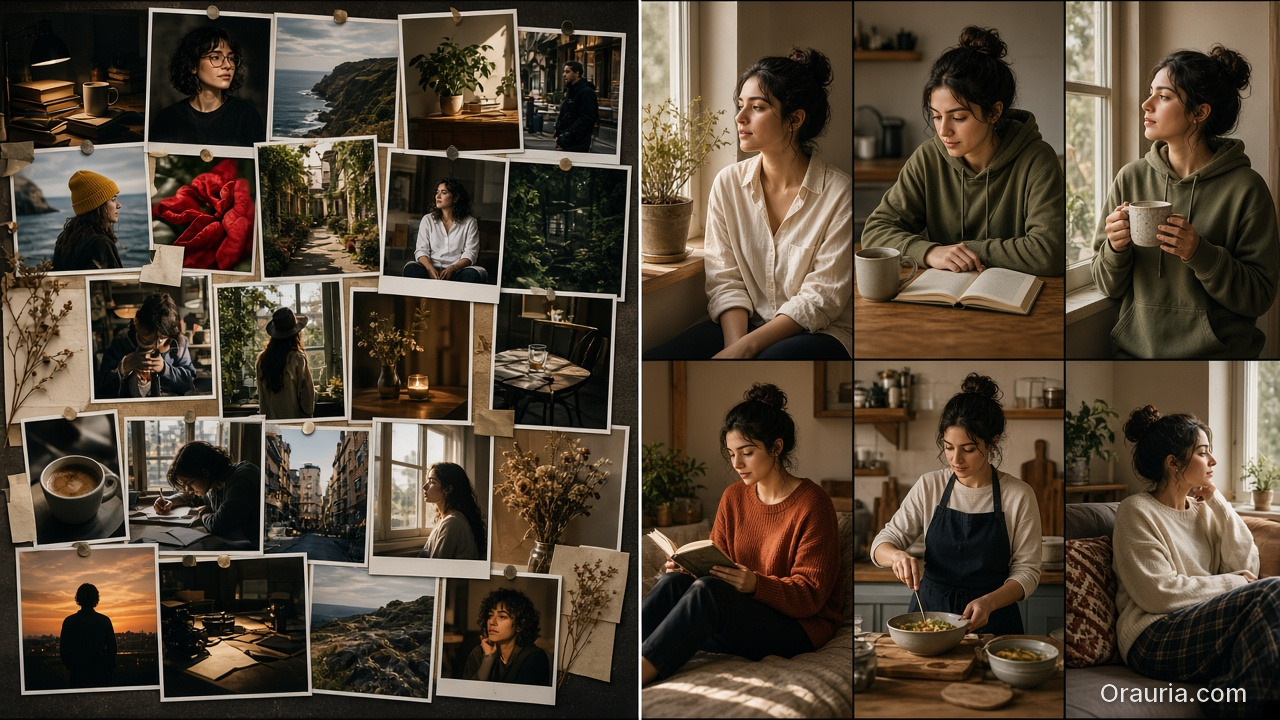
An AI content creator workflow that scales is a narrative system: a small set of arcs, a locked character/world kit, format slots that repeat, and weekly gates that protect coherence. One-off posts are expenses. Narrative systems are assets.
Key Takeaways
Buffer’s 26-week study of 100K+ users found creators who posted in 20+ weeks saw about 450% more engagement per post than those who posted in four weeks or fewer (Buffer, 2025–2026).
Consistency compounds more than heroic volume. Moving from sporadic to a steady weekly rhythm is the steepest gain curve.
A narrative system has four parts: arc, character/world kit, format slots, curator gate.
AI accelerates production inside the system. Without the system, AI accelerates sameness and drift.
Because each upload asks the audience to re-learn who you are.
One-off habit
Narrative system habit
New world every post
Recurring worlds
New face energy
Locked character kit
Hook without sequel
Arcs with episodes
Random formats
Slot map
Publish then forget
Weekly set review
Buffer’s consistency research is blunt: showing up across weeks beats rare spikes. Creators who posted consistently for 5–19 weeks still earned about 3.4× more engagement per post than the least consistent group. AI does not change that math. It only makes it easier to produce volume that still fails to compound.
Algorithms distribute posts. Audiences distribute memory. Narrative systems optimize for memory; one-offs optimize for the next upload anxiety.
What Is a Narrative System for Creators?
A narrative system is a reusable production architecture:
Arc — the story season (4–8 weeks)
Kit — character, palette, light, product rules
Slots — repeating format jobs (feed, Story, Reel, banner…)
Gate — who can reject “pretty but off-brand”
It is SCENE at calendar scale. Each episode gets a brief. The season gets a bible.
Build the Arc Before the Prompt
Pick one season thesis (one sentence)
Examples:
30 days of desk-lunch upgrades for busy founders
One outfit, eight lives — wardrobe as world-building
From shelf photo to craving — F&B education for DTC buyers
If you cannot say the thesis without commas, you have three arcs pretending to be one.
Define episode types (not topics)
Episode type
Job
Cadence
Hook
New viewer entry
1–2× / week
Proof
Trust / demo
1× / week
Depth
Save / share
1× / week
Soft CTA
Convert
1× / week
Community
Reply / stitch fuel
ongoing
Topics rotate inside types. Types stay stable. That is how an AI content creator workflow stays recognizable when tools change.
The Kit: What Must Repeat So Stories Can Change
Without a kit, every episode renegotiates identity — the brand consistency trap in creator form.
Adobe’s 2026 Creators’ Toolkit Report found 57% of creators still edit AI outputs moderately or extensively before publish. Editing inside a kit is craft. Editing without a kit is damage control.
Format Slots: Produce Once, Ship Many
Do not invent a new production for every ratio. Assign jobs:
Slot
Ratio
Narrative job
Feed
1:1 or 4:5
Episode poster
Story
9:16
Behind-the-arc / poll
Reel
9:16
Motion beat of the episode
Carousel
multi
Proof sequence
Banner / email
wide
Season reminder
Marketplace / store
compliance + brand
Always-on identity
This is the creator version of marketplace banner thinking — one master, many jobs — not twelve unrelated renders.
Weekly Operating Rhythm
A sustainable default for most creators in 2026 is not “post until collapse.” Buffer and industry frequency guides cluster meaningful gains around steady weekly presence, with many teams landing near 3–5 posts/week as a quality-safe band depending on platform.
Example week inside a narrative system
Day
System action
Output
Mon
Arc check + 3-line briefs
4 episode briefs
Tue
Generate masters in one kit
6–10 frames
Wed
Adapt slots (crop/extend)
Feed + Story + Reel covers
Thu
Curator gate
Kill drift / keep winners
Fri
Publish + reply block
Posts + community
Sun
Set review + archive
Update kit with winners
Notice what is missing: “open AI and hope.” Hope is not a workflow stage.
It is a repeatable system for planning, generating, adapting, and publishing creator content with AI — built around arcs and kits, not isolated prompts.
How is a narrative system different from a content calendar?
A calendar schedules dates. A narrative system defines what must stay the same so scheduled posts accumulate meaning. You need both; calendar without system is a to-do list.
How long should a creator arc run?
Four to eight weeks is a practical season. Shorter arcs rarely compound. Longer arcs need mid-season kit reviews to prevent drift.
Do I need to post every day?
No. Buffer’s data emphasizes consistent weeks over extreme daily volume. A sustainable rhythm you can keep beats a heroic week you abandon.
Can freelancers use narrative systems for clients?
Publishing exceptions without updating the bible — “just this one off-brand Reel.” Exceptions become the new default in two weeks.
Conclusion
One-off AI posts spend attention. Narrative systems invest it.
Write a season thesis. Lock a kit. Define episode types. Fill format slots from masters. Gate the week as a set. Let AI multiply inside the rules — not rewrite the rules nightly.
The creators who win with AI in 2026 will not be the ones who generate the most. They will be the ones whose audience can finish the sentence: this is another chapter of…
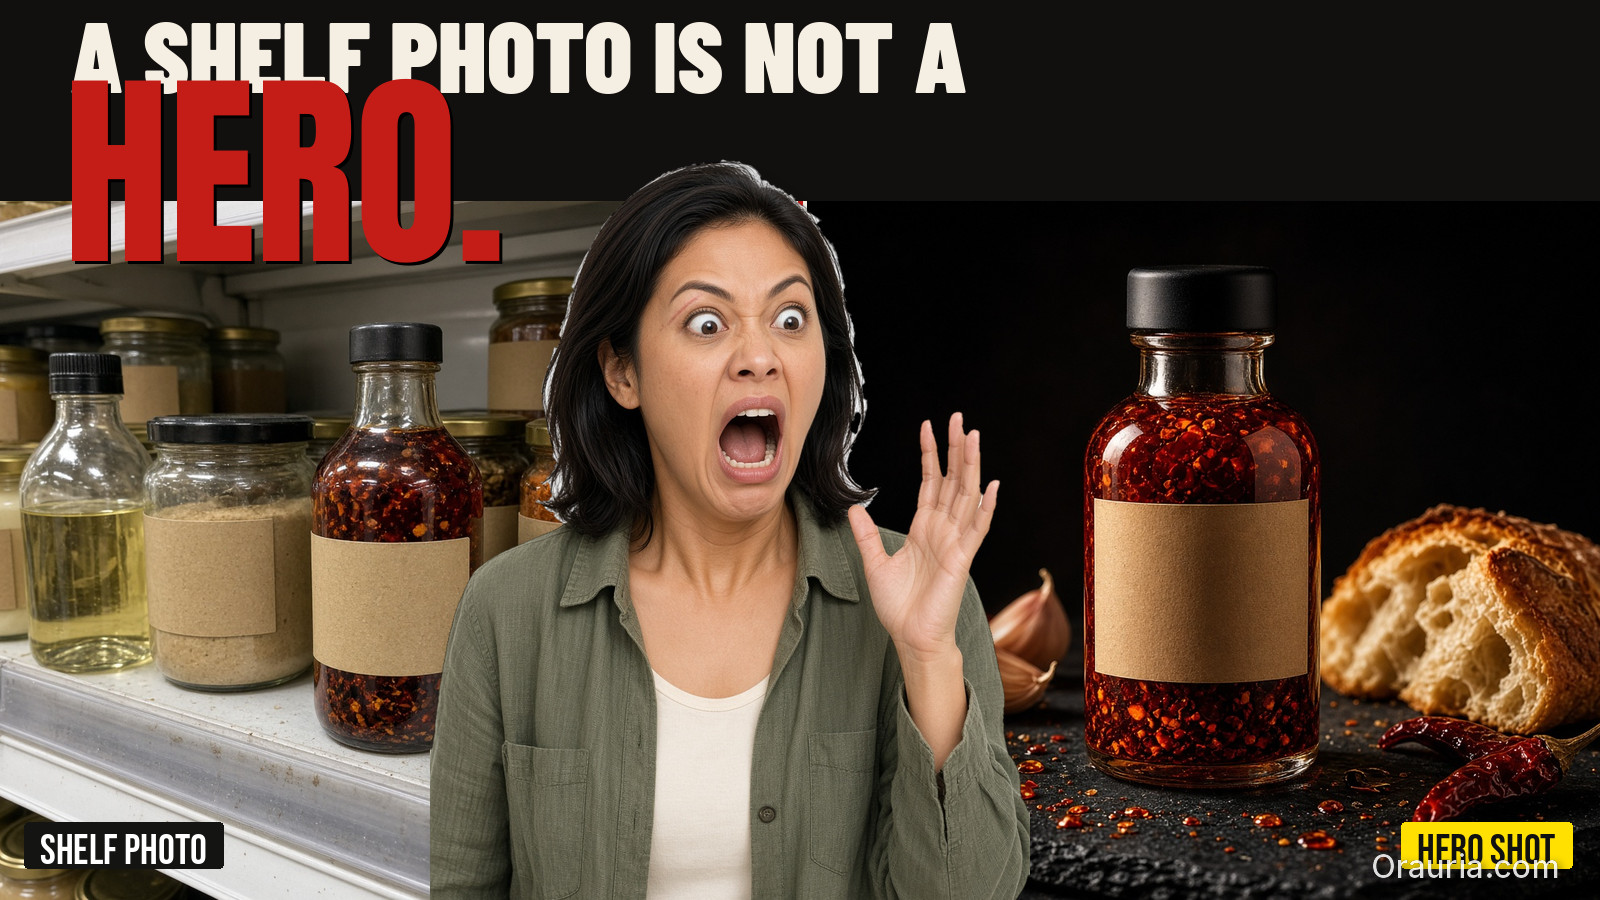
The photo starts on a phone, under fluorescent aisle light, next to three competing labels. By Friday someone asks for a “hero shot” for the PDP and a lifestyle scene for ads. The team pastes the shelf photo into an AI tool and prompts make it professional food photography. What comes back looks expensive — and wrong. Condensation in the wrong place. A label that almost matches. Steam that belongs to another dish.
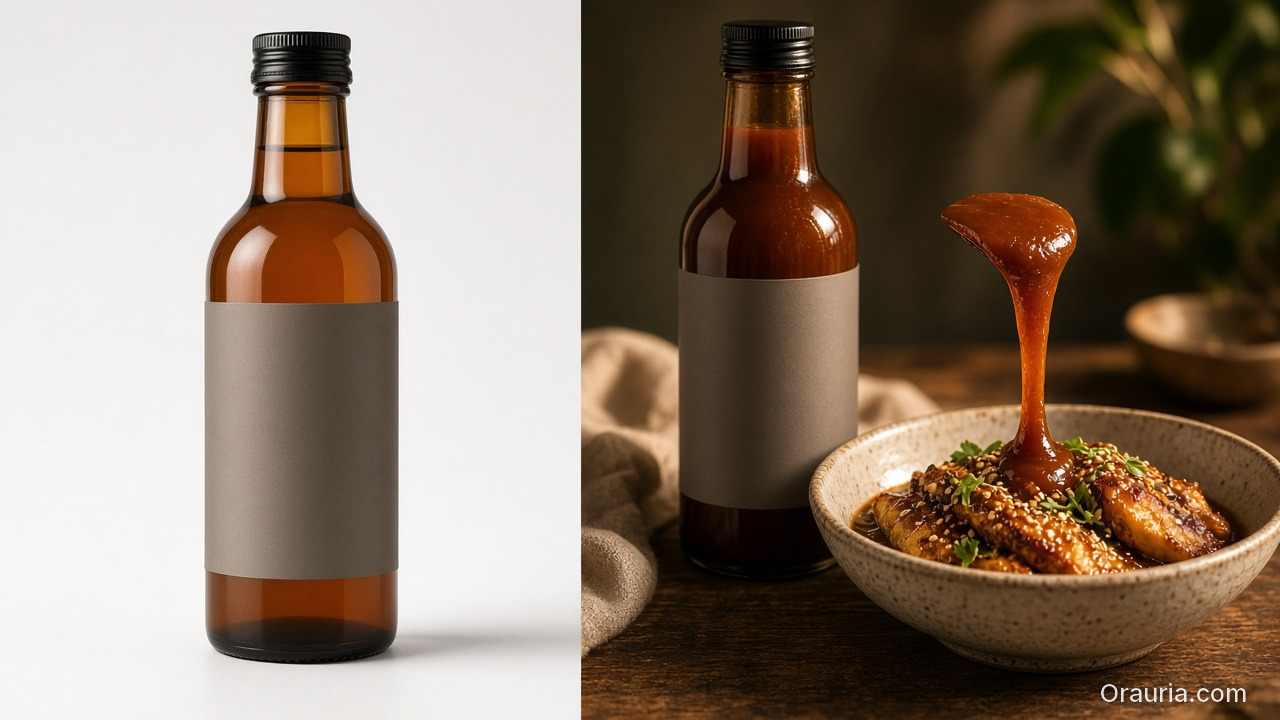
AI food product photography does not fail because shelf photos are low quality. It fails because teams skip creative direction: what job the hero must do, which appetite cues are non-negotiable, and which truths the label must keep.
Key Takeaways
Shelf photos are reference truth, not final creative. Treat them as geometry + label fidelity inputs.
Products with high-quality photos convert dramatically better than weak imagery — Salsify analysis cited across 2026 roundups puts the lift near 94% versus low-quality photos (Lumepixa / Salsify, 2026).
Listings with 5+ images show about 50% higher conversion than thinner galleries in large listing studies (Catchlab, via 2026 image stats roundups).
F&B heroes need a dual layer: compliance/clarity + appetite scene. White-only catalogs leave money on the table; fantasy-only heroes break trust.
A shelf photo answers one question: what is on the shelf?
A hero shot answers another: why should I crave this now?
Shelf photo job
Hero shot job
Identify SKU
Create appetite
Show real packaging
Stage desire + truth
Survive fluorescent light
Sell a moment
Capture available angles
Own the PDP first impression
AI that “beautifies” without a brief usually invents a third job: look like stock food. That third job converts poorly because it belongs to no brand and no meal occasion.
In F&B, the hero is not a prettier packshot. It is a negotiated truth: label fidelity plus appetite fiction that the product can still keep.
Condensation, pour, steam, crumb, melt — only if true to product physics
Hand or utensil for scale
Plating that matches the real serve
Light that matches the occasion (morning juice ≠ late-night chocolate)
Lifestyle additions commonly lift conversion in the 15–30% range over packshot-only layouts in industry A/B aggregates (2025–2026 ecommerce photography roundups). F&B is especially sensitive because appetite is emotional and returns are visual — items that “look different in person” remain a top return driver across categories.
From Phone Shelf Photo to Hero: A 7-Step Playbook
1. Shoot for reference, not Instagram
Straight-on label. Avoid heavy tilt. Include one 3/4 if the package has depth. Capture the barcode side only if needed for ops — not for the hero.
2. Write the non-negotiable label truths
Logo lockup, flavor name, regulatory marks, claim badges. If AI rewrites a word, the asset is dead for marketplaces.
3. Choose one appetite cue
Not five. Pick pour, steam, bite, condensation, or plating. Multiple cues usually look like a food-magazine collage.
4. Lock light logic
Cold drinks: cooler key, specular highlights. Bakery: warmer key, soft shadow. Spicy / savory: deeper contrast. Changing light mid-batch is how catalogs look like three restaurants.
5. Generate heroes from reference + brief
Use the shelf photo as product lock. Use the SCENE brief as world lock. If the model invents a new label, reject — do not “fix in Photoshop later” as a habit.
6. Build the five-image minimum
Catchlab-style listing research consistently favors richer galleries. A practical F&B set:
Clarity hero (truth)
Appetite hero (desire)
Serve / pour moment
Ingredient or texture macro
Lifestyle or table context
7. Channel-adapt before you regenerate
Crop the approved hero into Story and banner jobs. Regeneration is for new angles — not new identities of the same bottle. Same mindset as phone-to-campaign workflow.
What Must Never Drift in AI Food Imagery?
Element
Why it matters
Fail signal
Label typography
Legal + brand
Misspellings, melted letters
Package geometry
Recognition
Warped bottle / can proportions
Fill level / contents
Trust
Soup that looks empty; chips that look inflated
Allergen / claim badges
Compliance
Missing or invented marks
Food physics
Appetite credibility
Steam on iced drinks; melt on shelf-stable
Studio food photography still costs hundreds per SKU once styling and retouching enter the quote; AI compresses unit cost when direction is clear — industry writeups in 2026 routinely cite 60–80% cost reductions versus traditional shoots for catalog-scale work. Cost only helps if rejected assets stay rejected.
Occasion Mapping for F&B (Beauty’s Sister Grid)
Beauty maps rituals. F&B maps occasions:
Occasion
Hero cue
Avoid
Breakfast
Soft daylight, simple plate
Nightlife bokeh
Desk lunch
Compact, clean, portable
Banquet excess
Dinner share
Family board, steam
Clinical white only
Gym / recovery
Condensation, citrus, motion
Heavy garnish clutter
Gift / premium
Material, ribbon, quiet luxury
Street-food grit
Map 4–6 occasions for the brand, not per SKU. Then swap the product reference through the same worlds — batch thinking for catalogs that keep growing.
When Should You Still Book a Real Food Shoot?
AI direction wins for:
Catalog scale and seasonal flavor swaps
Channel crops and ad variants
Background / lifestyle exploration after label lock
Real shoots still win for:
Flagship hero campaigns where texture is the product (artisanal crumb, fresh seafood sheen)
Regulatory edge cases and packaging redesign launches
Hero SKUs where returns risk is extreme if appetite oversells
Hybrid is the default mature strategy — not ideology.
Can AI turn a phone shelf photo into a marketplace-ready hero?
Yes — if label truth is locked and the brief defines the hero job. Without those, AI produces pretty stock that fails compliance or trust.
How many images should an F&B PDP show?
Aim for at least five: clarity, appetite, serve, texture, context. Richer galleries correlate with stronger conversion in large listing studies.
What is the biggest AI mistake in food photography?
Inventing appetite cues the product cannot keep — fake steam, impossible melt, or garnishes that imply a different recipe.
Should every F&B SKU get a lifestyle scene?
Every hero SKU should. Long-tail SKUs can inherit occasion templates with swapped references once the brand kit is locked.
How is F&B different from beauty context mapping?
Beauty maps daily rituals on the same face/body. F&B maps meal occasions and food physics. Both need a grid before generation; the rows differ.
Do I need white-background shots for food marketplaces?
Often yes for the main image. Treat white as Layer A. Appetite scenes belong in secondary slots and ads — not as a replacement for truth.
Conclusion
Shelf photos are not the enemy. Undirected AI is.
Write the occasion. Lock the label. Pick one appetite cue. Build dual-layer galleries. Adapt approved heroes before you regenerate. Reject physics lies even when they look delicious.
AI food product photography becomes a growth system when creative direction arrives before the model — not after the disappointment.
You generate a strong face for Tuesday’s Reel. Wednesday’s Story looks related. Thursday’s carousel looks like a cousin. By Friday’s marketplace banner, followers comment: is that a different person?
That is not a model failure. That is a design failure.
AI character consistency is not a filter you toggle after the prompt. It is character design — the same discipline animation studios and game teams use before a single frame ships. Creators who treat the face as a lucky seed will keep losing identity across formats. Creators who write a character bible first can ship the same person across twelve placements without the audience noticing the pipeline.
Key Takeaways
Face consistency across formats is a character design problem, not a prompt trick. Lock identity rules before you open the generator.
Adobe’s 2026 Creators’ Toolkit Report found 57% of creators say AI outputs need moderate or extensive editing before publish — and 42% say AI-generated work makes distinctive voices harder to surface (Adobe, 2026).
A workable kit has three layers: character bible, reference pack, format map (12 placements, one identity).
Curator gates beat more seeds. One approved face family scales; twenty “almost right” faces destroy trust.
This is an industry playbook for creators, KOLs, and brand teams who put a human face in front of products. If you need the failure autopsy, read Brand Consistency Trap. If you need when to lock references versus explore, read Reference Images vs AI Explore. This article answers: how do you keep one face alive across twelve formats?
Why Does Face Drift Break Creator Trust Faster Than Bad Lighting?
Lighting mistakes look amateur. Face drift looks dishonest.
Followers forgive a soft shadow. They do not forgive a jawline that migrates every post. The brain treats facial identity as a continuity contract. Break it and engagement does not just drop — recognition resets. You are introducing a new spokesperson every week without meaning to.
Creators feel this as “the model changed my face again.” The deeper issue is upstream: there was no locked character. Every generation started from vibes instead of a bible.
Audience trust for AI-assisted creators is not “was this generated?” It is “is this the same person I already know?” Face consistency is continuity, not aesthetics.
What Is Character Design for AI Creators?
Character design means deciding — in writing and in images — what must never change, what may change, and what is forbidden.
Layer
Lock forever
Soft rules
Never do
Face geometry
Eye distance, jaw, nose bridge
Expression intensity
Age jumps, ethnicity drift
Hair
Base cut + color family
Styling for scene
Random length each post
Skin
Undertone, freckle map
Makeup level
Plastic smoothness one day, heavy pores the next
Wardrobe world
Signature palette
Outfit per format
Brand-clash logos
Age / era
Apparent age band
Season styling
Teen ↔ mid-30s oscillation
If you cannot fill this table in ten minutes, you are not ready to batch. You are ready to explore — once — then lock.
Citation capsule: Distinctive creator voices are already under pressure. Adobe’s 2026 survey found 42% of creators believe AI-generated work makes it harder for distinctive voices to surface. Face drift accelerates that problem by dissolving the one asset audiences use to recognize you.
The 12-Format Map: Same Face, Different Jobs
Consistency does not mean identical crops. It means identical identity under different jobs.
#
Format
Job
Face rule
1
Feed 1:1
Stop scroll
Full face, strong eye contact
2
Feed 4:5
Depth / product hold
Face + product in same plane
3
Story 9:16
Immersion
Closer crop, same bone structure
4
Reel cover
Click
Peak expression from approved set
5
Thumbnail
Search / browse
High-contrast, readable at 120px
6
Carousel keyframe
Sequence
Same lighting family across slides
7
Live avatar / talking head
Trust
Strict reference lock
8
Product demo still
Proof
Hands + face optional; no new identity
9
Marketplace banner
Store ID
Smaller face, brand-safe crop
10
Email hero
Click-through
Calm expression, clear silhouette
11
Ad variant A/B
Test hooks
Same face, different props only
12
Long-form cover
Authority
Most “portrait bible” accurate
Write the map once. Every new campaign inherits it. That is how narrative systems stay coherent when volume rises.
How Do You Build a Character Bible That Survives AI?
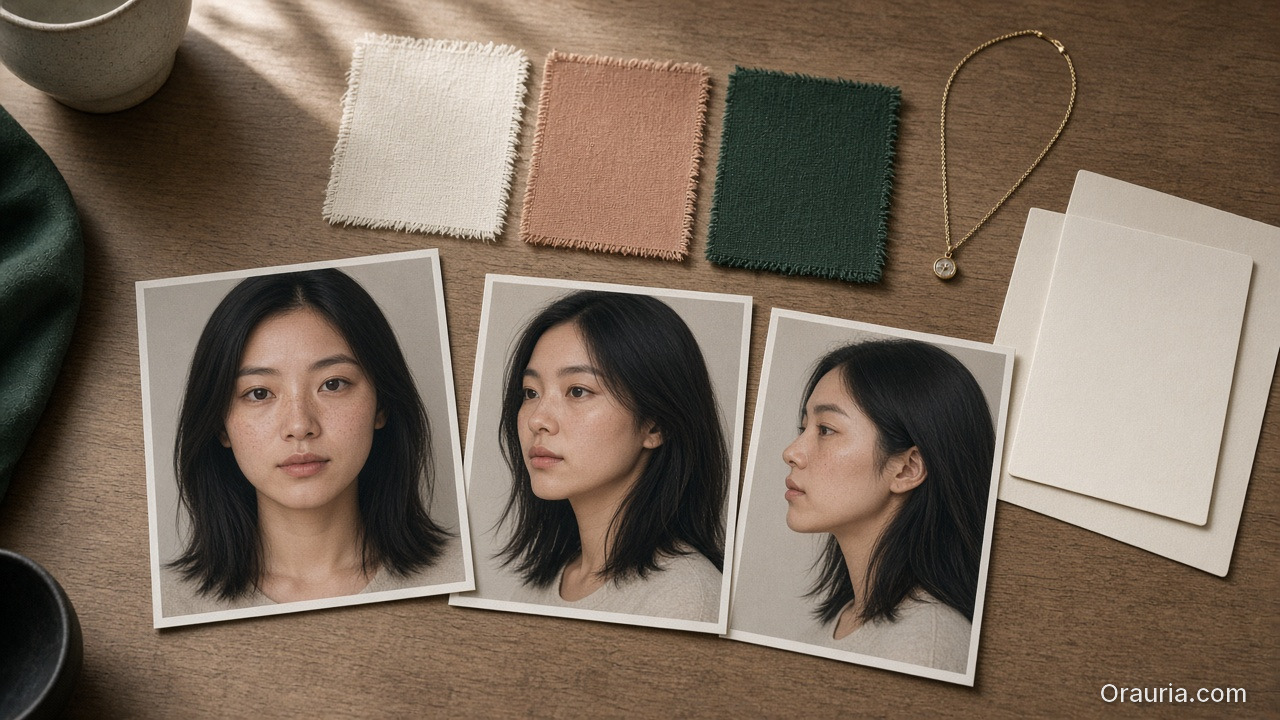
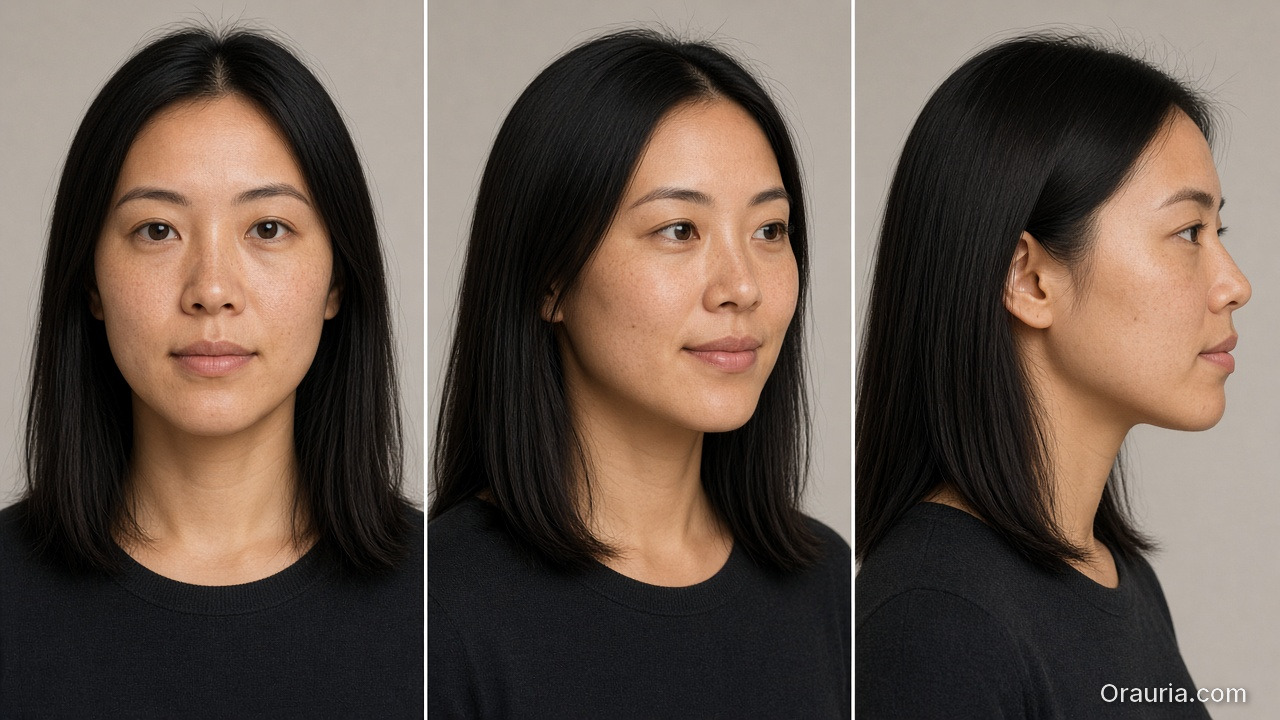
Step 1 — Capture three anchor references
Not twenty. Three:
Neutral front (passport energy)
Three-quarter with soft smile
Profile or strong side light
These become the identity spine. Everything else is a variation, not a rewrite.
Step 2 — Write the non-negotiables in one paragraph
Example: East Asian woman, apparent late 20s, warm undertone, soft freckles across nose bridge, straight dark hair to collarbone, almond eyes with slight monolid, no beauty marks, natural brows.
If the paragraph is longer than six lines, you are over-specifying fashion and under-specifying face.
Step 3 — Separate explore mode from production mode
Exploration is allowed before lock — moodboards, casting tests, style worlds. After lock, switch to reference-heavy mode. Production is not the time to “see what the model invents.”
Step 4 — Assign a curator gate
Someone (you, or a teammate) must reject outputs that break identity even if they look prettier. Pretty-but-wrong is how brands wake up with twelve spokespersons.
Gate
Pass
Fail
Bone structure
Matches anchors
Soften / reshape
Hair identity
Same family
New cut / color
Age read
Same band
Younger/older leap
Skin map
Same marks / freckles
Clean slate skin
Expression
Approved range
New “character personality”
Adobe’s finding that 57% of creators still edit AI outputs heavily is not a reason to skip direction. It is a reason to edit against a checklist, not against taste alone.
What Breaks Face Consistency in Practice?
Five patterns show up constantly in creator pipelines:
Prompt adjective stacking — “beautiful, glamorous, cinematic, ultra detailed” invites the model to redesign the face toward a beauty average.
Style refs stronger than face refs — a lighting moodboard overpowers identity when weights are wrong.
Format panic — regenerating from scratch for 9:16 instead of cropping/extending an approved master.
Multi-model hopping without re-locking — each model has a different face prior; hopping without anchors guarantees drift.
Batch publishing without a set review — each image looks fine alone; the grid looks like a casting call.
These map to the broader brand consistency trap. Face is simply the highest-stakes version.
Playbook: Ship One Face Across a Week of Content
Monday — Lock — approve three anchors + character paragraph
Monday — Map — fill the 12-format table for the week
Tuesday — Masters — generate 6–8 hero frames in one lighting family
Wednesday — Adapt — crop/extend masters into Story, Reel cover, banner; regenerate only when crop fails
When Should You Redesign the Character on Purpose?
Sometimes drift is a feature — new season, new brand deal, new persona arc. Redesign deliberately:
Announce the change in content (glow-up, season 2, brand collab era)
Rebuild anchors; do not “nudge” the old face into a new identity
Freeze the old kit; do not mix eras in the same week
Accidental redesign reads as error. Intentional redesign reads as storytelling — which belongs in your narrative system.
Soft CTA
Build character kits and format maps inside a production system, not twelve disconnected tabs. Explore Orauria’s creative workflow for ecommerce and creator teams: Orauria solutions · Gallery
Frequently Asked Questions
What is AI character consistency?
It is the practice of keeping the same facial identity, hair family, and age read across many generated images and formats. It is achieved with a character bible, reference anchors, and curator gates — not by hoping the next seed matches.
How many reference images do I need for a stable face?
Three strong anchors beat twenty weak ones. Add scene refs after identity is locked. More images help only when they reinforce the same person.
Can I keep one face across different AI image models?
Yes, if you re-lock with the same anchors in each model and treat the first approved outputs as the new production set. Hopping models mid-campaign without anchors is the fastest path to cousins.
Should every format show the full face?
No. Marketplace banners and some product demos may use smaller face presence or hands-only. The rule is: if a face appears, it must be the same face.
How is this different from brand consistency?
Brand consistency covers palette, light, and scene world. Character consistency is the human identity layer inside that brand. You need both; face drift can break a brand even when colors are perfect.
What is the biggest mistake creators make with AI faces?
Treating each post as a new casting session. Character design decides once, then produces many times.
Conclusion
Face consistency across twelve formats is not a prompt setting. It is character design — anchors, non-negotiables, format jobs, and a curator who rejects prettier lies.
Write the bible. Lock three references. Map the twelve placements. Adapt masters before you regenerate. Review the week as a set.
The creators who scale AI without losing their audience are not the ones with the luckiest seeds. They are the ones who decided who they are — then refused to renegotiate every Tuesday.
The listing looks soft on mobile zoom. Someone drops the file into an upscaler. Edges crisp. The logo grows new serifs. A seam appears that the product does not have. The marketplace still rejects the crop — or worse, accepts it and returns spike later.
AI product image upscale is not a magic “make HD” button. It is the Upscale node in a workflow: sharpen only what already passed geometry and label QA.
Key Takeaways
Upscale amplifies truth and lies equally. QA before sharpen.
Products with high-quality photos convert far better than weak imagery in 2026 roundups (Salsify-cited ~94% lift vs low-quality) — but “sharp fakes” are not high quality (Lumepixa, 2026).
Place Upscale after Generate gates in node thinking — never as forgiveness for a bad reference.
Marketplace min resolution is a delivery constraint, not a creative strategy.
Why Do Teams Upscale Too Early?
Because resolution is measurable and fidelity is judgment.
Early upscale habit
What actually happens
Soft phone photo → 4K
Soft lies become sharp lies
Rejected AI still → upscale
Warped type becomes confident warped type
Every crop upscaled
Hours spent polishing variants that should die
Upscale instead of reshoot/ref
Reference problem becomes production debt
Phone-to-campaign discipline still starts with a usable reference (workflow mindset). Upscale cannot invent a better capture — only a bolder one.
Marketplace buyers do not reward megapixels. They reward zoom that still matches the unboxing. Upscale without QA is how you fail that contract in high resolution.
The QA Gate Before Upscale
Run this checklist on the winner still only:
Geometry
Silhouette matches physical SKU
No melted corners, stretched labels, floating caps
Typography / print
Brand wordmarks readable and correct
No invented ingredients, seals, or stars
Material
Fabric / plastic / glass reads plausible
No “plastic skin” or fake micro-contrast
Compliance
Background rules for the target marketplace
Required margins for the crop job
Fail any row → regenerate or recapture. Do not upscale.
The Slack thread starts the same way every week: “Should we use Veo, Kling, or Seedance?” Nobody has written the shot list. Nobody has locked the product reference. Nobody has decided whether the clip is a hook, a demo, or a proof. Credits disappear. The cut still feels generic.
Choose the AI video model after creative direction. Model choice is a bottleneck decision — the same rule as choosing an image model, applied to motion.
Key Takeaways
Video model debates fail when the job is undefined. Define scene job, duration, audio need, and product fidelity first.
Adobe’s 2026 Creators’ Toolkit Report found 57% of creators still edit AI outputs moderately or extensively before publish — video is not exempt (Adobe, 2026).
Match models to bottlenecks: cinematic continuity, product-locked motion, fast ad variants — not brand loyalty to a name.
Keep Crop / cutdowns as a node, not a new identity
If the still fails label QA, no video model will “fix” it honestly.
Playbook: One Hour Before You Spend Credits
Write 3-line brief + scene job
Attach brand kit + product ref
Decide strict vs flexible fidelity
Pick path: T2V vs I2V
Route to model family by bottleneck
Generate 2–3 takes max before curator gate
Edit for job — do not regenerate to avoid editing
Adobe’s edit-rate data is a reminder: plan the gate. Do not outsource judgment to the next seed.
Soft CTA
Explore motion and stills inside one creative workspace after direction is clear: Gallery · Studio Guide
Frequently Asked Questions
What is the best AI video model for ecommerce ads?
There is no universal best. The best model is the one that fits your bottleneck after creative direction — fidelity, speed, cinematic language, or audio.
Should I pick the video model before the image model?
No. Lock still direction and product truth first when the clip is product-led. Awareness films can start from text, but ecommerce usually should not.
Is image-to-video always safer for products?
Safer for identity when the still is approved. Not automatic — motion can still warp labels. Gate outputs.
How is this different from choosing an image model?
Same principle, different failure modes. Video adds duration, camera language, and audio. The order — direction before model — stays identical.
How many models should a team standardize on?
Usually one default per bottleneck, not one model for everything. Document the routing sheet so freelancers do not reinvent it weekly.
Conclusion
Veo vs Kling vs Seedance is a late question.
Job, truth level, duration, audio, source path — then model. Choose the AI video model after creative direction, the same way you choose image models after the brief. Direction is strategy. Models are routing.
You launch in one language. Then marketplace ops asks for EN, VI, TH, and ID versions of the same banner by Friday. Someone regenerates the whole scene four times. The bottle changes shape. The light shifts. The brand kit quietly dies.
AI ecommerce image localization is not “translate and pray.” It is a production rule: one visual master, many language layers — with gates that protect SKU truth and brand identity across borders.
Key Takeaways
Rebuild-per-language is how catalogs fracture. Localize text and claims, not the entire world, unless the market truly needs a new scene.
High-quality product imagery remains a conversion lever in 2026 roundups (Salsify-cited lifts vs weak photos); localization must not destroy that quality (Lumepixa, 2026).
Treat localization as a node after Brand Style + Generate — never as a fresh creative brief.
Legal claims, units, and badge rules are market-specific gates — not prompt adjectives.
Why Do Per-Language Regenerations Break Brands?
Because generation optimizes for a new pretty frame, not for identity continuity.
Rebuild-per-language
Master + localize
New light each market
Same light family
Label drift risk × N
One Truth gate
Four art directions
One kit
Slow QA
Diff-check text regions
Cross-border teams do not need more models. They need batch thinking applied to locales.
Localization fails when teams translate campaign vibes instead of translating claims. Vibes can stay global. Claims must go local.
What Should Stay Global vs Go Local?
Keep global (master layer)
Product geometry and packshot truth
Brand palette and light logic
Scene world / lifestyle context (unless culturally wrong)
Character identity if a face is used
Localize deliberately
In-image headlines and CTAs
Promotional badges and price callouts
Measurement units and regulatory lines
Marketplace-required disclaimers
Redesign only when required
Cultural taboo in scene
Model casting rules by market
Category compliance that forbids the original composition
If you redesign every time, you do not have a localization system. You have N brands.
Playbook: Master → Locale Pack
Step 1 — Ship a language-agnostic master
Prefer compositions with clear text safe zones (marketplace banner thinking). Avoid burning essential claims into tiny packaging type you cannot legally alter.
Step 2 — Extract a claim sheet per market
Field
EN
VI
Notes
Hook line
…
…
Char limit
Offer badge
…
…
Color locked
Unit line
oz
ml
Compliance
Disclaimer
…
…
Legal review
Step 3 — Localize as a gated node
Input: approved master + claim sheet. Output: locale variants. Gate: geometry unchanged, brand kit intact, text correct, no new product.
Step 4 — Diff review, not vibes review
Flip EN ↔ VI on the same crop. If the bottle moved, reject — even if Vietnamese typography looks nicer.
Step 5 — Archive locale packs with the kit
Next drop swaps SKU refs, reuses locale claim templates. That is how cross-border catalogs scale.
Where AI Helps — and Where It Lies
Helps: rapid text replacement in safe zones, layout fitting, bulk varianting after master lock.
Lies: rewriting packaging legal text “to look native,” inventing certificates, changing ingredient panels, or “improving” the product silhouette while translating.
Packshot honesty still applies (packshot thinking). A localized ad that misrepresents the SKU creates returns in every language.
It is the practice of adapting in-image text and market claims on a locked visual master so catalogs stay consistent across languages and marketplaces.
Should every market get a unique lifestyle scene?
Only when culture or compliance demands it. Default to one world, many language layers.
Can AI translate text printed on the product package?
Treat package print as high risk. Prefer accurate photography of the real SKU for Truth frames; localize marketing overlays separately.
How do I QA localized images quickly?
Side-by-side diff against the master. Check geometry first, typography second, claim accuracy third.
Where does this sit in a workflow builder?
After Generate and before Upscale/Crop variants — localization should not invent a new product.
Conclusion
Cross-border growth should multiply locales, not multiply identities.
Lock a master. Write claim sheets. Localize as a node. Diff-check like a skeptic. Keep the bottle the same bottle.
That is AI ecommerce image localization that scales — without quietly founding a new brand in every language.